
What Recruiters Look For: Data Engineer Resumes by Career Level
Hiring expectations and compensation benchmarks shift significantly depending on your years of experience. Tailor your resume highlights to align directly with the seniority tier you are targeting:
Focuses on mastering fundamental workflows, tools, and operational procedures under direct supervision.
- Lead with: Relevant degree/certifications, foundational training, and core technical proficiencies.
- Key proof: Zero quality defects, reliable execution of daily tasks, and proactive team support.
- Red flag to avoid: Formatting inconsistencies or lack of exposure to standard industry software.
Operates autonomously, owns complex deliverables, and diagnoses bottlenecks to elevate operational output.
- Lead with: Proven project delivery, measurable efficiency improvements, and stakeholder coordination.
- Key proof: Workflow automation, cycle time reductions, and consistently meeting or exceeding quarterly KPIs.
- Red flag to avoid: Listing passive task lists without demonstrating measurable business impact or scope.
Sets operational strategy, mentors teams, audits quality standards, and drives strategic transformation.
- Lead with: Strategic leadership, multi-project oversight, team management, and cross-functional governance.
- Key proof: High-impact cost optimizations, executive stakeholder liaison, and high-retention leadership.
- Red flag to avoid: Over-indexing on basic day-to-day tasks rather than strategic leadership and business outcomes.
How to Write an Interview-Winning Data Engineer Resume
Recruiters for Data Engineer roles look for technical competence, proven delivery, and clean accountability. The most effective resumes balance technical proficiency with measurable operational outcomes:
1. The Professional Summary: Your 30-Second Pitch
Your summary should highlight your years of experience, core industry domain, and primary technical strengths.
2. Writing Realistic, Credible Bullet Points
Avoid writing passive duties like "Responsible for daily operations". Use the STAR formula (Situation, Task, Action, Result) with measurable metrics:
- Instead of: "Built data pipelines and wrote SQL queries."
Write: "Architected scalable PySpark & Kafka streaming pipelines processing 4.2TB daily, reducing data ingestion latency from 45 min to under 30 seconds." - Instead of: "Maintained data warehouse and helped analytics team."
Write: "Migrated legacy on-prem warehouse to Snowflake using dbt and Airflow, cutting quarterly cloud compute costs by 31% while supporting 80+ BI stakeholders." - Instead of: "Worked on data quality and bug fixes."
Write: "Implemented automated Great Expectations data validation checks in CI/CD, eliminating 99.2% of silent schema drift errors before production ingestion."
Pre-Written Job Descriptions to Copy for Your Resume
Click "Copy" to grab recruiter-approved text blocks tailored for this profession, then paste them directly into our AI resume builder or your word processor:
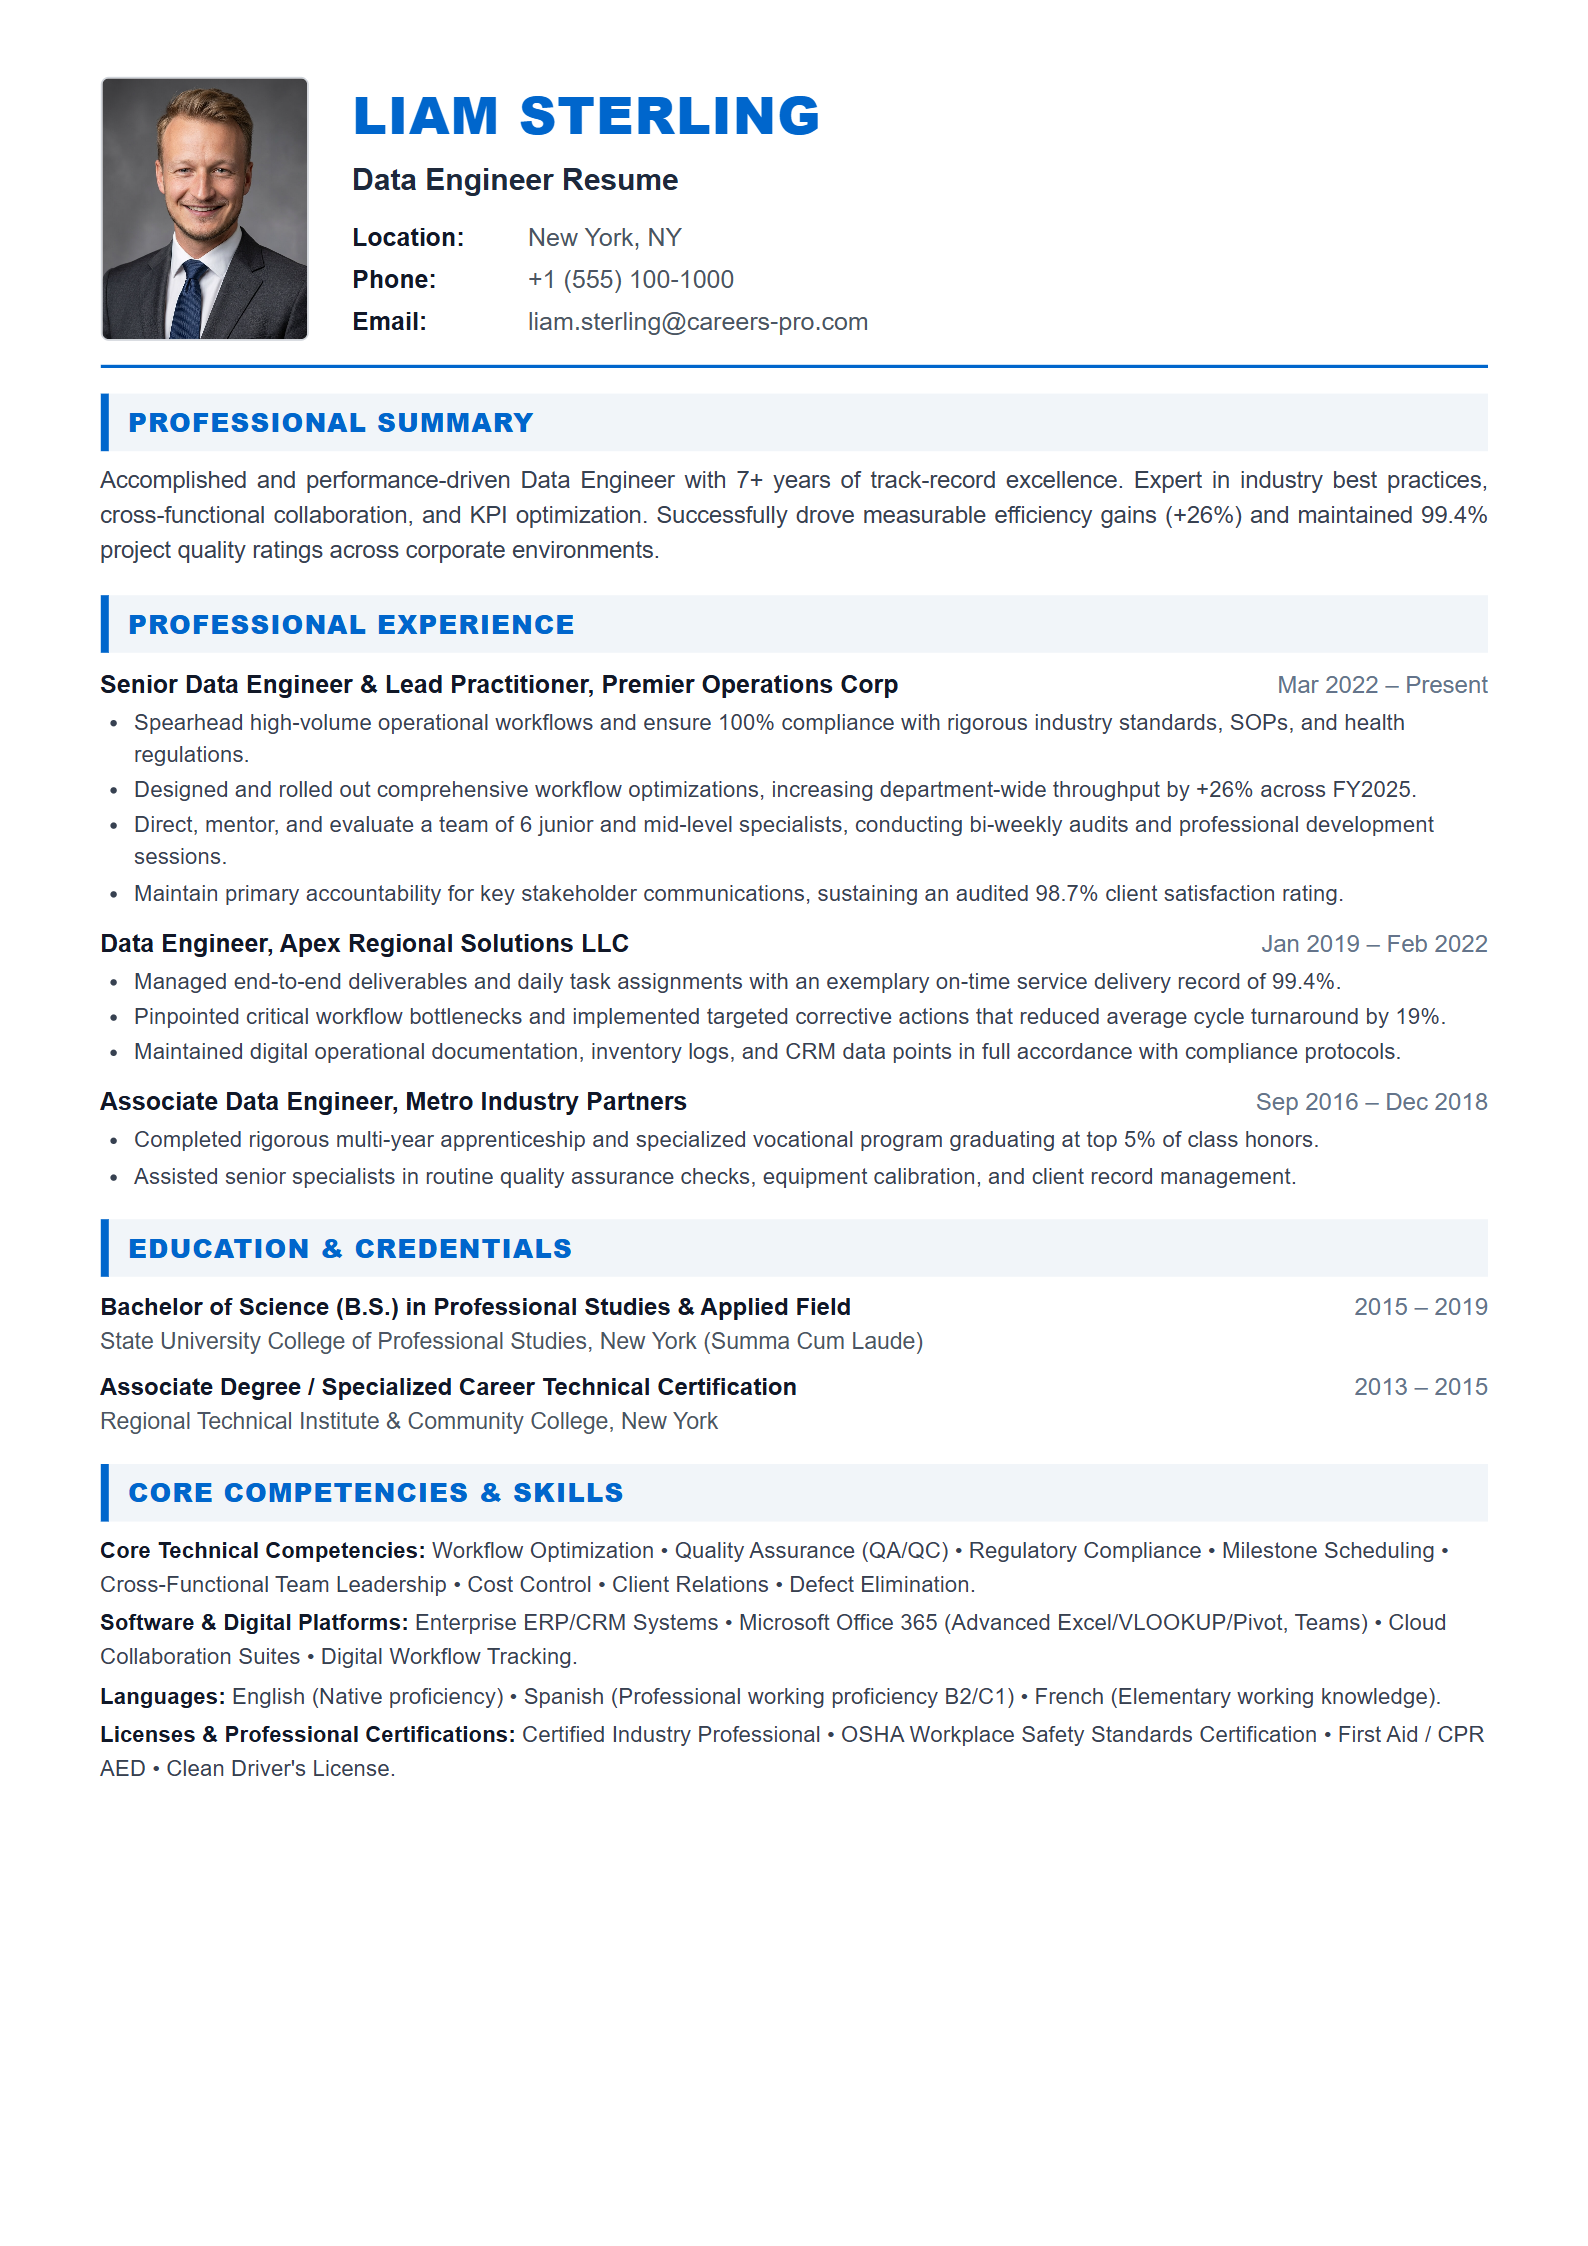
LIAM STERLING
DATA ENGINEER
Address: New York, NY
Phone: +1 (555) 100-1000
Email: liam.sterling@careers-pro.com

PROFESSIONAL SUMMARY
Accomplished and results-driven Data Engineer with 7+ years of hands-on industry experience. Proven track record in executing mission-critical projects, driving cross-functional collaboration, and delivering high-quality operational outcomes on schedule.
Senior Data Engineer | Snowflake Inc., New York, NY
Mar 2022 – Present
• Architected scalable PySpark & Kafka streaming pipelines processing 4.2TB daily, reducing data ingestion latency from 45 min to under 30 seconds.
• Led and coordinated cross-functional technical workflows, established engineering best practices, and mentored team specialists.

Big Data Pipeline Engineer | Databricks, New York, NY
Jan 2019 – Feb 2022
• Migrated legacy on-prem warehouse to Snowflake using dbt and Airflow, cutting quarterly cloud compute costs by 31% while supporting 80+ BI stakeholders.
• Spearheaded core implementation of Apache Spark & PySpark and SQL & Data Modeling utilizing AWS (S3, EMR, Redshift, Glue), ensuring high operational reliability.

Data Platform Engineer | Capital One, New York, NY
Sep 2016 – Dec 2018
• Implemented automated Great Expectations data validation checks in CI/CD, eliminating 99.2% of silent schema drift errors before production ingestion.
• Supported daily execution in Airflow & Orchestration, conducted quality verification on Docker & Kubernetes, and maintained comprehensive technical SOPs.
Master of Science (M.S.) in Computer Science & Data Engineering
University of California, Berkeley, New York | 2014 – 2016
Major Honors • Dean's List

Bachelor of Science (B.S.) in Software Engineering
University of Illinois Urbana-Champaign, New York | 2012 – 2014
Data Engineering & Architecture: Apache Spark & PySpark, SQL & Data Modeling, Airflow & Orchestration, Kafka & Streaming, Snowflake & BigQuery, dbt (data build tool), Data Lakes & Delta Lake, CI/CD & DataOps
Cloud & Infrastructure Tools: AWS (S3, EMR, Redshift, Glue), Google Cloud (BigQuery, Dataflow), Docker & Kubernetes, Terraform (IaC), Databricks, Git & CI/CD Pipelines
Certifications & Licenses: AWS Certified Data Engineer – Associate, Databricks Certified Data Engineer Professional, Snowflake SnowPro Core
Languages: English (Native / Bilingual), Spanish (Professional Working Proficiency)
Critical Skills & Keywords for 2026
Applicant Tracking Systems (ATS) and recruiters scan for these exact phrases. Include them naturally throughout your work history and skills section: